papers

List of papers and talks

2026

  1. PRO (AAAI-26)
    pro_logo.svg
    Probabilities Are All You Need: A Probability-Only Approach to Uncertainty Estimation in Large Language Models
    Manh Nguyen, Sunil Gupta, and Hung Le
    The 40th Annual AAAI Conference on Artificial Intelligence, 2026
    TL;DR: Estimates predictive entropy from top-K output-token probabilities with an adaptive K; +2.4% avg AUROC over the best baseline across 3 QA datasets.
  2. RAD (ECML 2026)
    rad_logo.svg
    Retrieval-augmented Decoding for Improving Truthfulness in Open-ended Generation
    Manh Nguyen, Sunil Gupta, and Hung Le
    2026
    TL;DR: Builds a tiny reference store of truthful logits from  10 examples to steer decoding; +3.2% avg truthfulness on TruthfulQA, no retraining.
  3. RCS
    rcs_logo.svg
    Efficient Best-Of-N with Radial Consensus Score
    Manh Nguyen, Sunil Gupta, and Hung Le
    2026
    TL;DR: Ranks sampled LLM answers by distance to their embeddings’ semantic center; +2-7% selection accuracy over strong baselines incl. majority voting.
  4. UAB
    uab_logo.svg
    Uncertainty-Aware Budget Allocation for Adaptive Test-Time Reasoning
    Manh Nguyen, Sunil Gupta, and Hung Le
    2026
    TL;DR: Reallocates a fixed sampling budget toward harder questions using early-round disagreement as a difficulty signal; +2.3% avg accuracy over uniform allocation (up to +5.5% peak).
  5. DAR
    darlogo.webp
    Hear Both Sides: Efficient Multi-Agent Debate via Diversity-Aware Message Retention
    Manh Nguyen, Anh Nguyen, Dung Nguyen, and 2 more authors
    2026
    TL;DR: Each round, broadcasts only the most disagreeing agent responses instead of every message, cutting multi-agent debate noise while keeping useful diversity.
  6. TB-MAD
    tbt_overview.svg
    Think More or Read More? A Token-Budget Theory of Reasoning with Shared Context
    Manh Nguyen, Sunil Gupta, and Hung Le
    2026
    TL;DR: Predicts the optimal number of debate agents from single-agent measurements alone; self-consistency matches or beats debate in 93% of 980 settings under tight token budgets.
  7. VCA
    vca_overview.png
    Volatility-Clustering Adaptation for Financial Time Series
    Manh Nguyen, Minh Hoang Nguyen, Huu Hiep Nguyen, and 2 more authors
    2026
    TL;DR: Adds an autocorrelation penalty on squared returns to the training loss so rollouts match real volatility clustering; improves over the pretrained model, strongest under FORE evaluation.
  8. SPaCe (ACL-26)
    space_overview.png
    SPaCe: Unlocking Sample-Efficient Large Language Models Training With Self-Pace Curriculum Learning
    Dai Do, Manh Nguyen, Svetha Venkatesh, and 1 more author
    The 64th Annual Meeting of the Association for Computational Linguistics, 2026
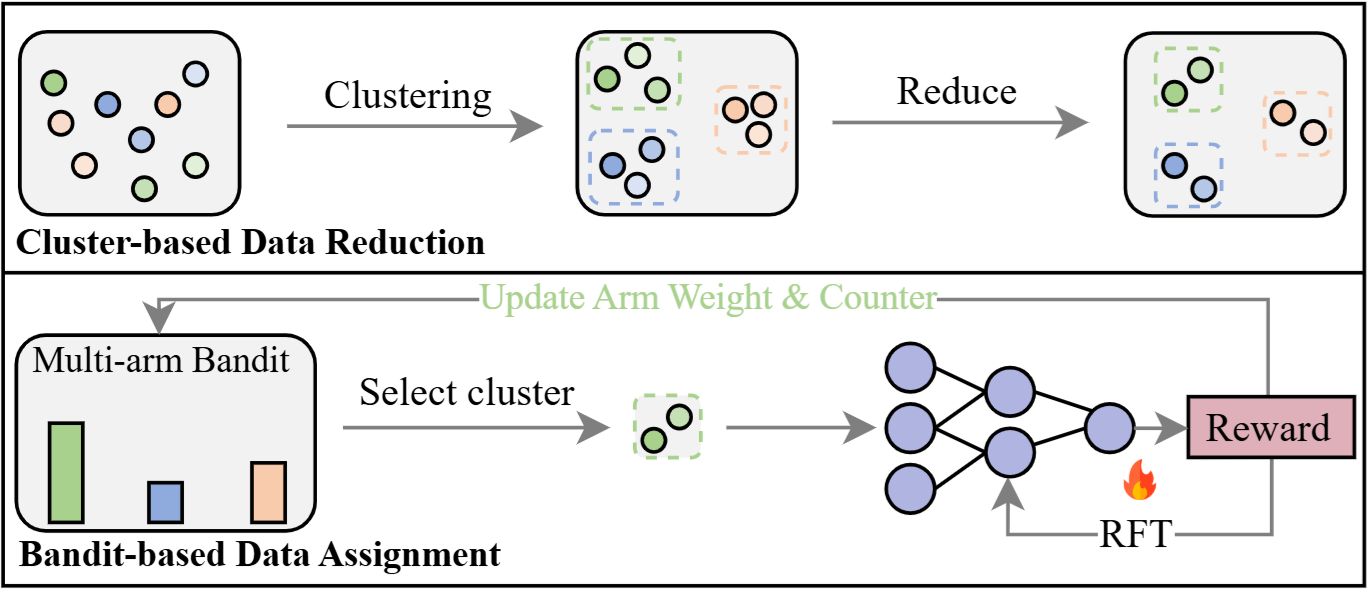
    TL;DR: A self-paced curriculum: clusters training data by difficulty/semantics, then a bandit allocates samples by solve rate; matches SOTA accuracy with up to 100x fewer samples.

2025

  1. GRAD
    grad_logo.svg
    GRAD: Graph-Retrieved Adaptive Decoding for Hallucination Mitigation
    Manh Nguyen, Sunil Gupta, Dai Do, and 1 more author
    2025
    TL;DR: Blends a small retrieved token graph’s evidence with the model’s own predictions at decoding time; up to +9.7% accuracy, -8.6% hallucination vs. greedy decoding.
  2. UGCS
    ugcs_overview.png
    Uncertainty-Guided Checkpoint Selection for Reinforcement Finetuning of Large Language Models
    Manh Nguyen, Dung Nguyen, Dai Do, and 2 more authors
    2025
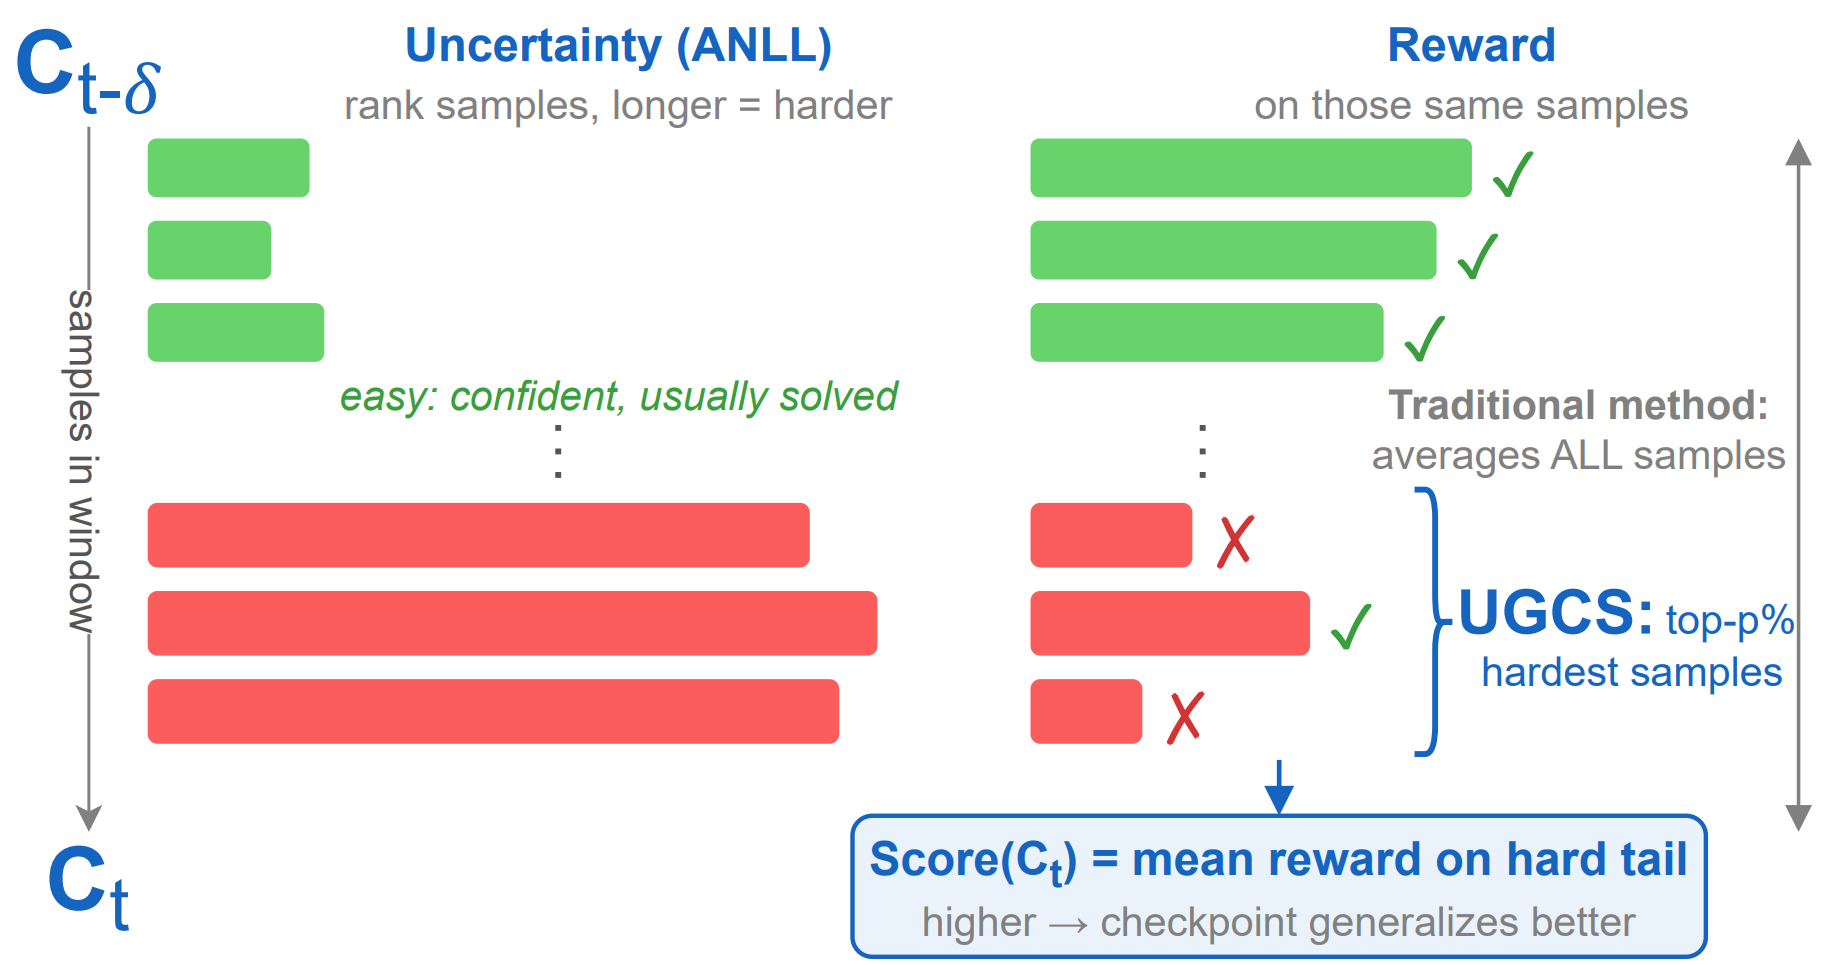
    TL;DR: Ranks RL-finetuning checkpoints by reward on the hardest, highest-uncertainty samples instead of overall validation score; more reliable than training/validation-based selection.
  3. JoMA-25
    Topic classification of vietnamese product reviews in e-commerce using PhoBERT
    Tuan Duy Nguyen, Duc Minh Nguyen, Manh Nguyen, and 1 more author
    Journal of Marketing Analytics, 2025
    TL;DR: PhoBERT embeddings + logistic regression classify 17K Shopee reviews into 5 topics (quality, service, price, shipping, packaging); F1 = 0.96, Hamming loss = 0.022.
  4. RDS
    rds.png
    Distance Is All You Need: Radial Dispersion for Uncertainty Estimation in Large Language Models
    Manh Nguyen, Sunil Gupta, and Hung Le
    2025
    TL;DR: A training-free uncertainty score: embeds sampled generations on a hypersphere and measures their spread from the mean; beats 9 SOTA baselines on hallucination detection.
  5. preprint
    factcheck_overview.png
    Towards Robust Fact-Checking: A Multi-Agent System with Advanced Evidence Retrieval
    Tam Trinh, Manh Nguyen, and Truong-Son Hy
    2025
    TL;DR: Four cooperating agents (claim decomposition, query generation, evidence retrieval, verdict) for automated fact-checking; +12.3% Macro F1 over baselines on FEVEROUS/HOVER/SciFact.

2019

  1. CinC2019
    cinc2019_aecnet.png
    Representation Learning for Early Sepsis Prediction
    Luan Tran, Manh Nguyen, and Cyrus Shahabi
    Computing in Cardiology, Apr 2019
    TL;DR: AEC-Net: an LSTM autoencoder (reconstruction loss) plus a classifier head for early sepsis prediction; scored 0.284 utility on the hidden PhysioNet/CinC 2019 test set (24th place).

talks

  1. 3MT (People's Choice Award)
    3MT (People's Choice Award)
    From Confident Lies to Trusted Answers — a Three Minute Thesis talk on trustworthy AI